AI usage
Admin → AI usage shows what the AI features cost.
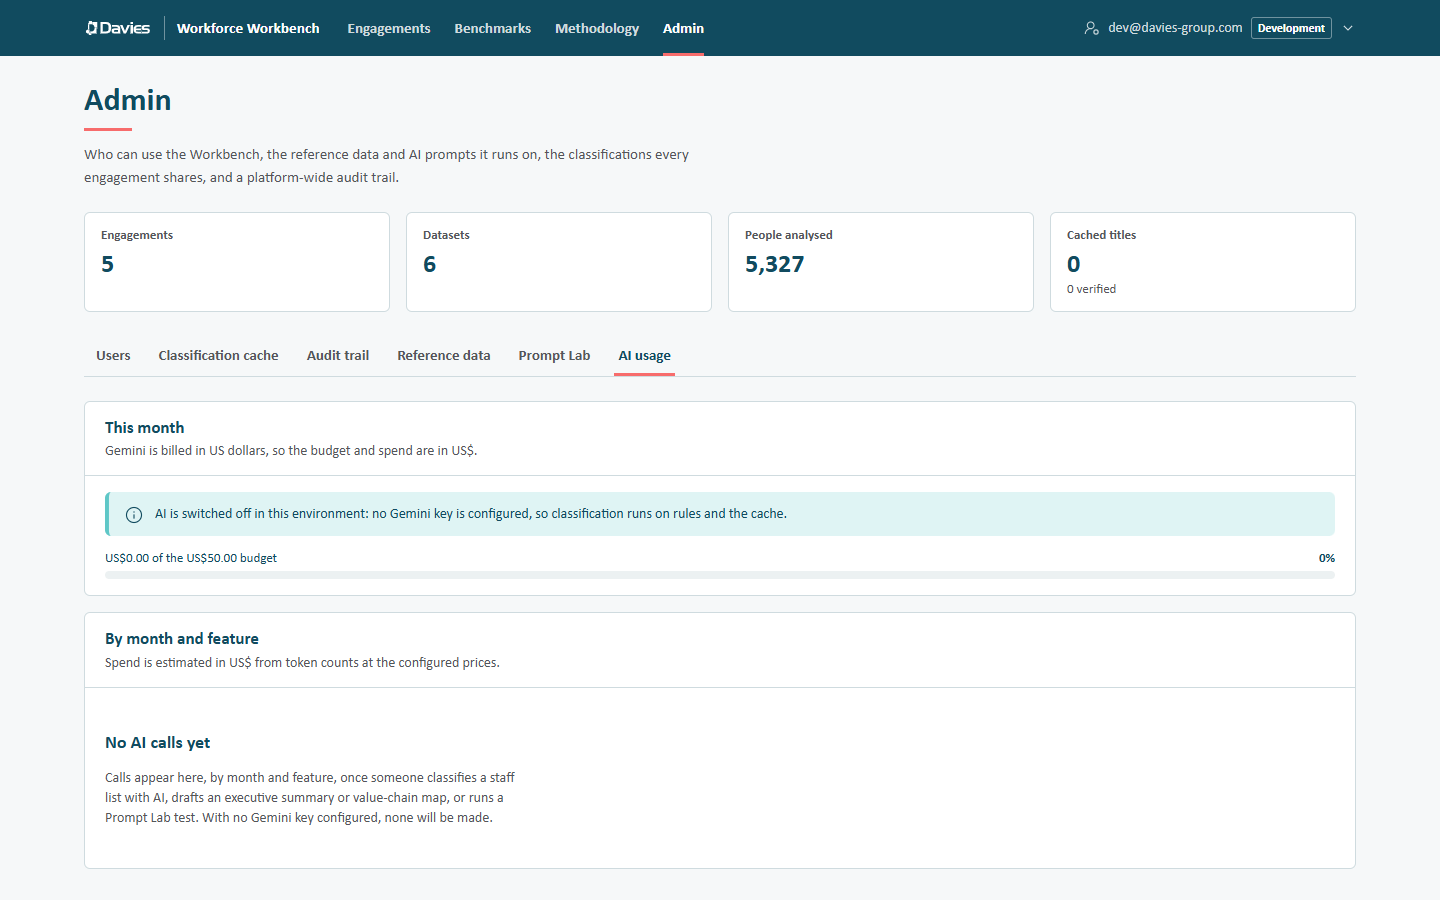
This month
- The model in use, for example
gemini-3.1-flash-lite, and that Gemini is billed in US dollars, so the budget and spend are in US$. - A progress bar: US$12.40 of the US$50.00 budget, with the share spent.
- A warning at 80% of the budget (Over 80% of the monthly budget is spent.), and at 100% The monthly budget is spent, so AI features are paused.
If AI isn't configured on the environment, the page says so: AI is switched off in this environment: no Gemini key is configured, so classification runs on rules and the cache.
By month and feature
The last twelve months of usage, by Month and Feature, with Calls, Input tokens and Output tokens. Features:
| Feature shown | What it is |
|---|---|
| Title classification | AI title classification during upload. |
| Executive summary | Write with AI / Regenerate on the executive summary. |
| Value-chain map | Map with AI on the value chain. |
| Ask the data | Ask this workforce questions. |
prompt-lab | Run test in the Prompt Lab (previews are free and not recorded). This one is shown by its internal name. |
Spend is estimated in US$ from token counts at the configured prices, per million input and output tokens. It's an estimate for the guardrail, not an invoice. When there's nothing to show, the card says No AI calls yet.
When the budget is spent
The budget is platform-wide and resets on the 1st of each month (UTC). When month-to-date spend reaches it:
- AI classification stops for the rest of the month; uploads carry on with overrides, industry packs, the shared cache and the rules, and say why;
- Write with AI, Map with AI and Prompt Lab test runs explain that the budget has been reached (This month's AI budget (US$50) has been reached., quoting the configured budget), and the rule-based text stays;
- Ask this workforce replies with the same explanation.
To resume sooner, raise AI_MONTHLY_BUDGET_USD on the deployment (see the developer guide's configuration).
A prompt version can name its own model in the Prompt Lab. Spend is still estimated at the platform's configured prices, so a prompt that uses a more expensive model is under-estimated here.